Investment AI Needs Versioned Skills, Not Open-Ended Self-Improvement
A new SEC-filing QA workflow treats recurring agent errors as scoped, testable patches. That is a more investable operating model than letting an agent rewrite itself.

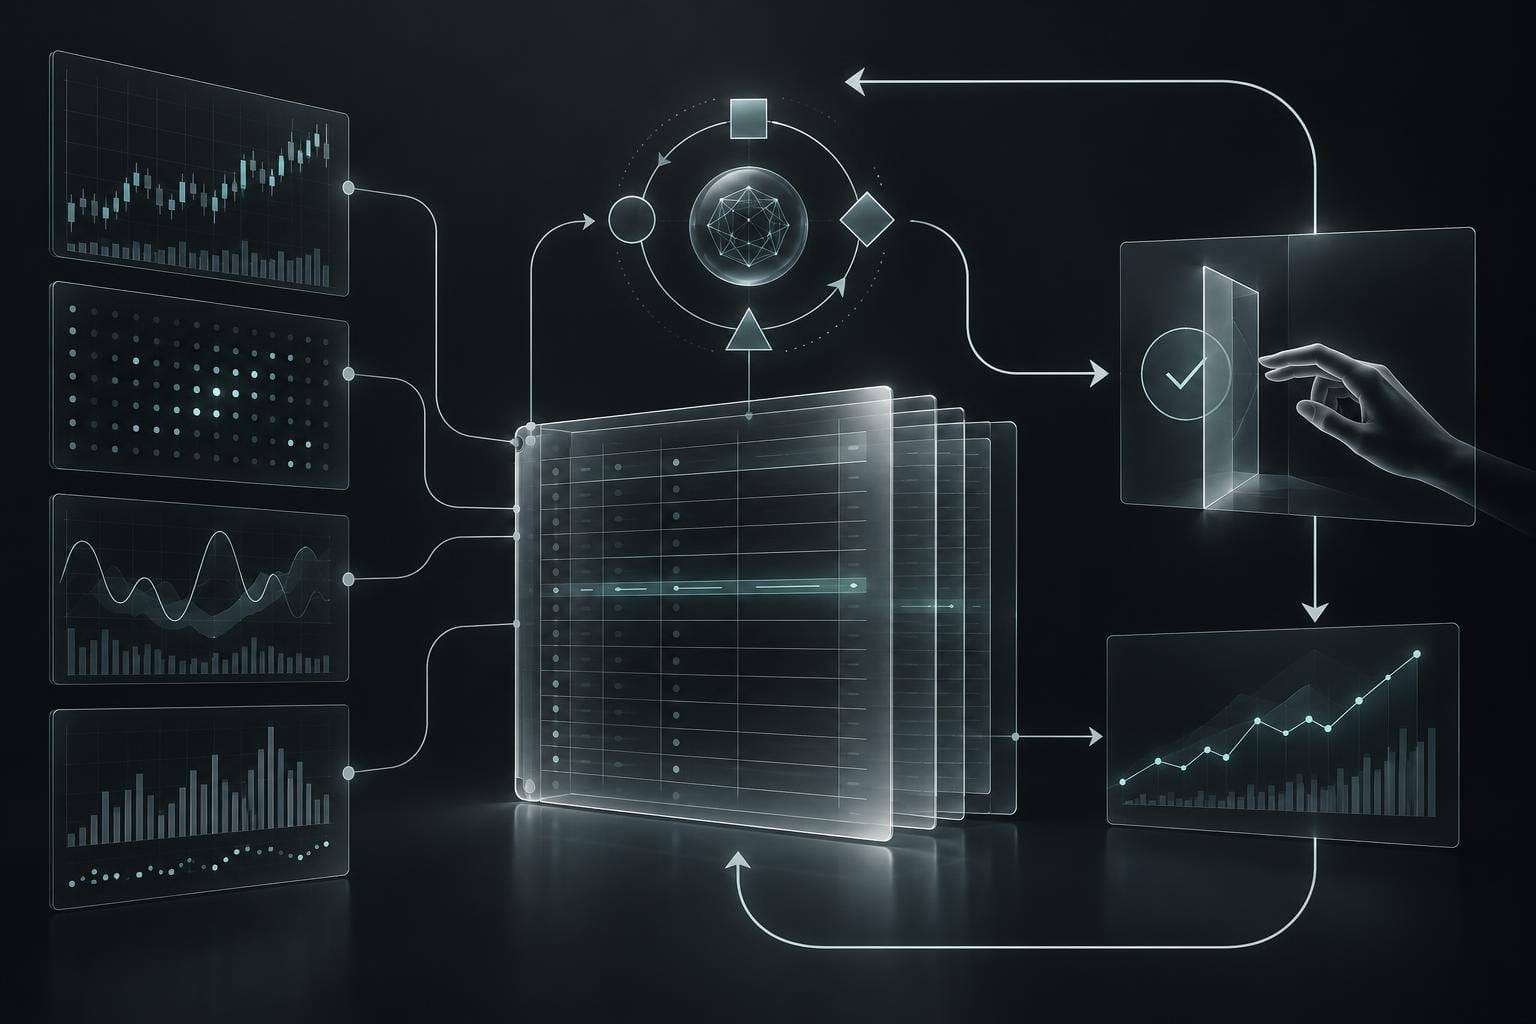
The useful question for an investment agent is no longer only whether it can answer a filing question. It is whether the system can improve after an error without quietly changing answers that were already right. A September 17 paper, FINSKILLOPS: A Self-Evolving Multi-Agent System for SEC Filing QA, makes that operational problem concrete: recurring failures become scoped skill patches, and each patch must pass targeted validation, protected-case regression checks, negative controls, and versioned replacement or retirement (paper).
My judgment: this is a better frontier for investment AI than “self-improving” as a slogan. In research, the scarce asset is not another fluent answer. It is a trustworthy change log showing what the system learned, where the change applies, and what it might have broken.
The workflow changed from prompting to maintenance
The old workflow treats a bad answer as a prompt problem. An analyst adds an instruction, reruns the question, and hopes the improvement generalizes. The new workflow treats the error as a typed maintenance event: wrong reporting period, wrong entity, unsupported evidence, arithmetic failure, or a calculation that mixed incompatible units. A diagnosis produces a small behavior patch—say, “identify the filing period before extracting a growth rate”—rather than a broad instruction to “be more careful.”
That changes the unit of investment research automation. A team can now maintain a registry of behaviors alongside its model and retrieval stack. Each registry entry has a scope, an example that motivated it, a test set, an owner, a version, and a retirement rule. The agent may propose a patch, but a controlled process decides whether the patch enters production.
This is adjacent to the evidence discipline in AI filing triage and the auditable earnings-call queue: the output is valuable only when a human can reconstruct why an item appeared and which source supports it.
What an investable implementation looks like
For a filing-research assistant, the loop can be reproduced with ordinary components:
- Capture every rejected answer with the question, entity, period, retrieved passages, calculation trace, and model version.
- Classify the failure before proposing a fix. “Wrong period” and “missing evidence” should not create the same behavior.
- Generate a narrow patch with explicit scope and a counterexample—an input on which the new rule should not fire.
- Run the patch on the triggering cases, a protected set of previously correct cases, and negative controls drawn from neighboring tasks.
- Promote only if the evidence trail improves without unacceptable regressions; otherwise revise, quarantine, or retire it.
The paper reports an encouraging but bounded result: in its operational study, only six of 33 proposed skills were promoted. That rejection rate is a feature, not a weakness. It says the system distinguishes a plausible correction from a safe production change. The reported benchmark gains are evidence about that paper’s setup, not proof that a similar registry will improve every investment workflow.
The SEC’s public filing corpus is a natural test bed because documents carry dates, entities, amendments, tables, and footnotes. Yet the same structure creates traps. A patch trained on one issuer’s unusual presentation may overfit its language. A rule that improves annual-report questions may harm earnings releases. A retrieval change can alter the evidence set before the “skill” is even evaluated. Every result therefore needs a receipt: source document, page or table location, time of access, transformation, and answer.
A 60-minute research-only exercise
Use 20 historical SEC filings from three companies and one fixed question, such as identifying the reported revenue and period for a named segment. Do not trade, place orders, or use the result as advice. First run the unmodified assistant on 20 questions and record exact-match answer accuracy, evidence-supported accuracy, unsupported-claim rate, and median number of retrieval/tool calls. This is the baseline.
Then select one recurring failure, write one narrowly scoped patch, and test it on the original 20 questions, 10 protected questions that were initially correct, and 10 negative controls where the patch should not apply. Observe for 30–60 minutes. Stop if the patch cannot cite the relevant filing passage, if protected-case accuracy falls by more than 10 percentage points, or if the assistant starts producing confident answers when the document is ambiguous. The output is a patch card and a regression table—not a forecast or a trading signal.
The limits are the point
This workflow does not remove model risk. Selection bias enters when the team logs only visible failures; survivorship bias enters when retired patches disappear from reports; measurement bias enters when “correct” means plausible text rather than a verified figure and period. A benchmark can also reward the patch’s expected format. Production incentives matter: a vendor may prefer a high acceptance rate, while an investment team should prefer a high rejection rate when the cost of a false correction is large.
Causality is similarly weak. Better answers after a patch may reflect easier questions, cleaner documents, or a changed retrieval index rather than a durable capability. Non-stationarity remains: filings, accounting presentation, and analyst questions change. A safe system preserves old cases, timestamps every evaluation, and periodically reopens its assumptions.
For discretionary investors, the lesson is to ask for evidence receipts and a change log. For systematic teams, it is to version research behavior as carefully as code and data. For builders, it is to make “self-improvement” a gated maintenance pipeline with explicit failure classes, not an agent permission to rewrite its own operating rules. The frontier is not an agent that never errs. It is a research workflow that can learn from an error without hiding the cost of learning.
Sources: FINSKILLOPS (arXiv:2609.19680); SEC EDGAR company filings.