AI Investment Research Needs a Disclosure Audit Before It Becomes Workflow
AI can compress investment disclosure review, but the durable workflow is an auditable claim ledger—not a confident summary.

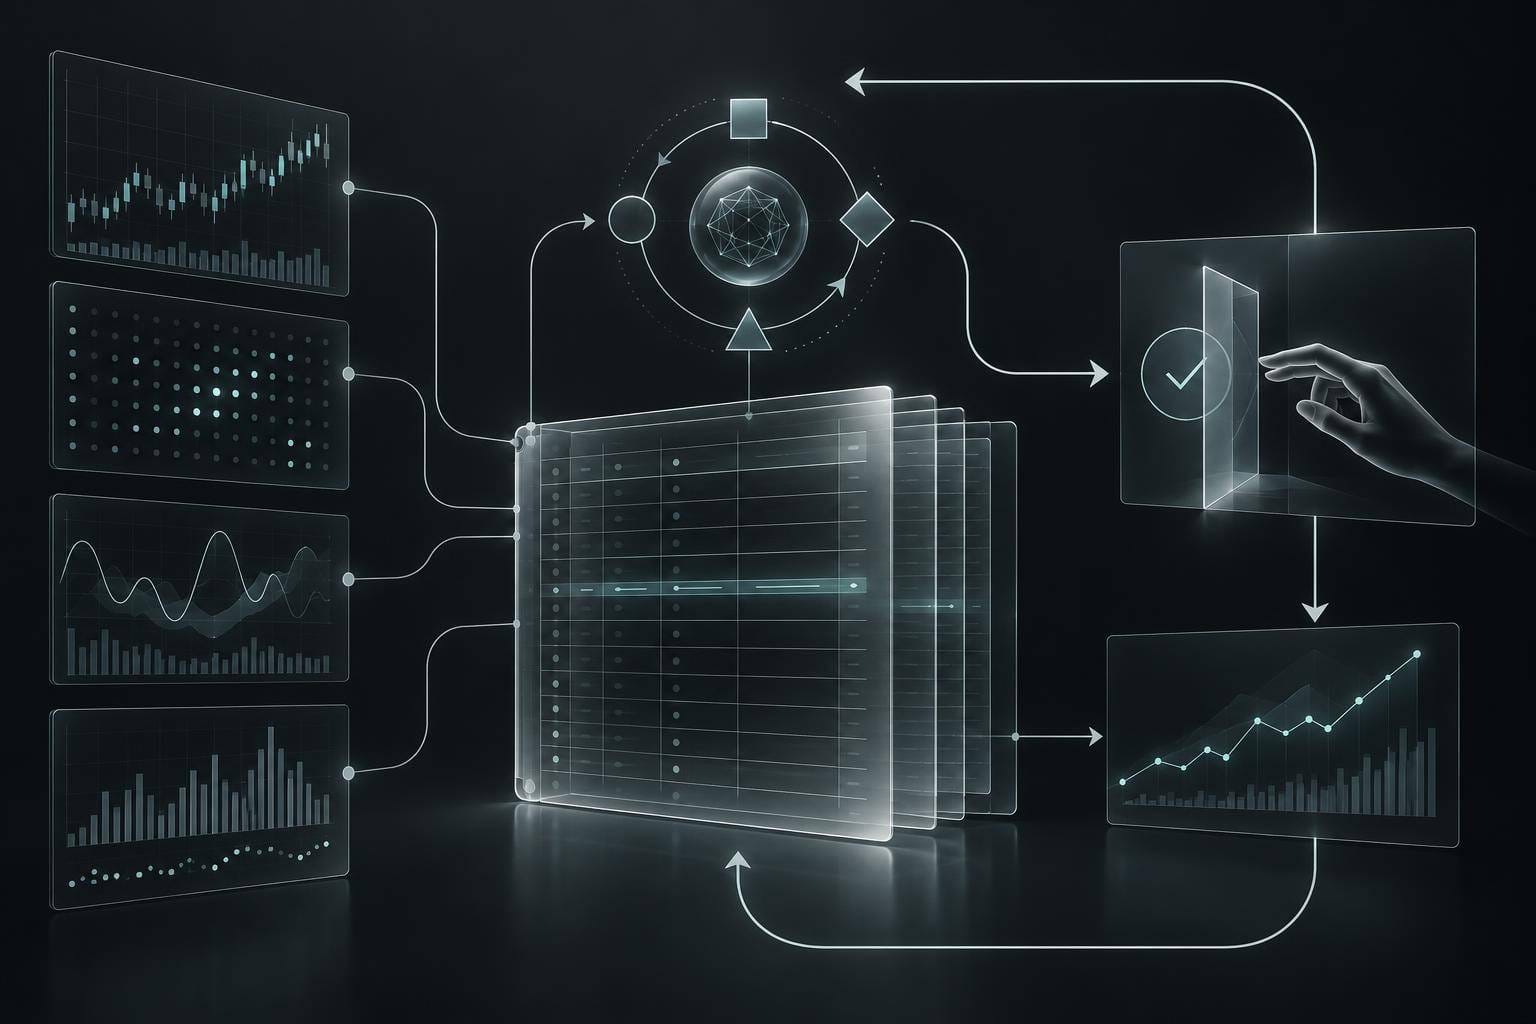
The investment-research workflow is changing in a less glamorous place than prediction: disclosure review. An analyst can now ask an AI system to extract changes, obligations, and unresolved questions from a filing or compliance document. That reduces the cost of forming a first-pass map. It does not make the map reliable by itself.
The useful unit of work is therefore not an AI-generated summary. It is a disclosure audit: every material claim gets a source location, a date, a confidence label, and a human decision about what remains unverified. The SEC’s recent discussion of “information in the age of AI” is a reminder that AI-related costs and responsibilities can move through advisers, funds, intermediaries, and ultimately investors (SEC). A separate SEC examination alert emphasizes that advisers must review whether their compliance policies are adequate and working in practice (SEC risk alert). Together, they point toward a workflow question: can an AI-assisted review leave enough evidence for someone else to challenge it?
From reading a document to maintaining a claim ledger
The old process is linear: open a filing, search for relevant terms, highlight passages, write notes, then circulate a memo. The new process can be staged. First, freeze the document version and metadata. Second, ask the model to identify candidate claims under fixed headings: change, exposure, obligation, assumption, missing data, and escalation question. Third, require a short quotation or table reference for every candidate. Fourth, have a human reviewer reject unsupported claims and mark the remainder as confirmed, plausible, or unresolved.
That sequence changes the output. The model is not being asked to decide whether a development is good for an investment. It is helping produce a structured queue of things a researcher can verify. This is closer to the auditable research queue described in the earlier workflow guide than to an autonomous analyst.
The practical benefit is not speed alone. It is a better separation between evidence and interpretation. A useful record contains the document hash or stable URL, retrieval timestamp, page or section, extracted claim, model wording, reviewer correction, and the next question. If a conclusion changes, the team can see whether the evidence changed, the interpretation changed, or the model simply produced a different answer.
That emphasis on provenance complements the series’ earlier discussion of reproducible research trails: an AI-assisted review is only useful when another person can reconstruct the path from document to judgment.
What the model can and cannot do
AI is good at candidate generation, normalization, and comparison when the input corpus is bounded. It can find repeated risk language, align two reporting periods, and turn long prose into a review queue. It is weaker at deciding materiality, resolving ambiguous definitions, detecting what a document omits, or understanding whether management language is strategically evasive. A fluent answer can also hide a source mismatch: the model may combine periods, confuse an estimate with an outcome, or infer causality from correlation.
For that reason, prompts should require abstention. “No supporting passage found” is a valid result. So is “claim depends on an unavailable exhibit.” The reviewer should also inspect a sample of negative results, not only the findings that look important. Otherwise selection bias enters at the first screen: the workflow measures what the model surfaced, not what existed.
A 60-minute research-only test
Use one public filing or investor-relations disclosure and one earlier comparable document. Do not place an order, change a portfolio, or treat the output as advice.
Baseline: a researcher’s ordinary 30-minute review, recording the number of material claims found, the number later verified, and the time required to produce a short evidence table.
AI condition: give the model the same two documents, require section-level citations and an abstain option, then spend 30 minutes reviewing its table. Measure citation precision (supported claims divided by sampled claims), missed material changes found by the human, correction count, time to a review-ready table, and inter-reviewer agreement on materiality.
Keep the observation window to this one session, or repeat the test across seven comparable document pairs. Stop if the model cannot provide stable source locations, if reviewers cannot reproduce its claims, or if unsupported claims exceed the team’s predefined tolerance. The purpose is workflow measurement, not a forecast or a return estimate.
The uncomfortable limits
This test does not establish that AI improves investment outcomes. The sample may be selected for clean documents; survivors are easier to process than messy disclosures. Human reviewers may reward concise prose, creating measurement bias. A model vendor may have incentives to emphasize coverage while the investment team has incentives to report efficiency. Documents can be revised, links can disappear, and a later restatement can invalidate a previously reasonable conclusion.
There is also a causal gap. Better traceability may improve review quality, but it does not prove better allocation decisions. Costs, latency, confidentiality, access rights, and compliance controls can dominate any apparent productivity gain. A ledger can make a bad judgment easier to audit; it cannot make the judgment correct.
The durable lesson for discretionary investors is to practice claim-level verification. Systematic teams should treat extraction quality and abstention as monitored model metrics. Builders should make provenance, versioning, and reviewer correction first-class outputs rather than optional interface features. The frontier is not an AI that sounds like an analyst. It is an investment workflow that can show exactly where the analyst—or the model—might be wrong.