Agentic Trading Needs a Paper-Trading Ledger Before It Needs Capital
As AI agents move closer to market access, the investment workflow changes from writing a backtest to auditing a closed-loop decision process.

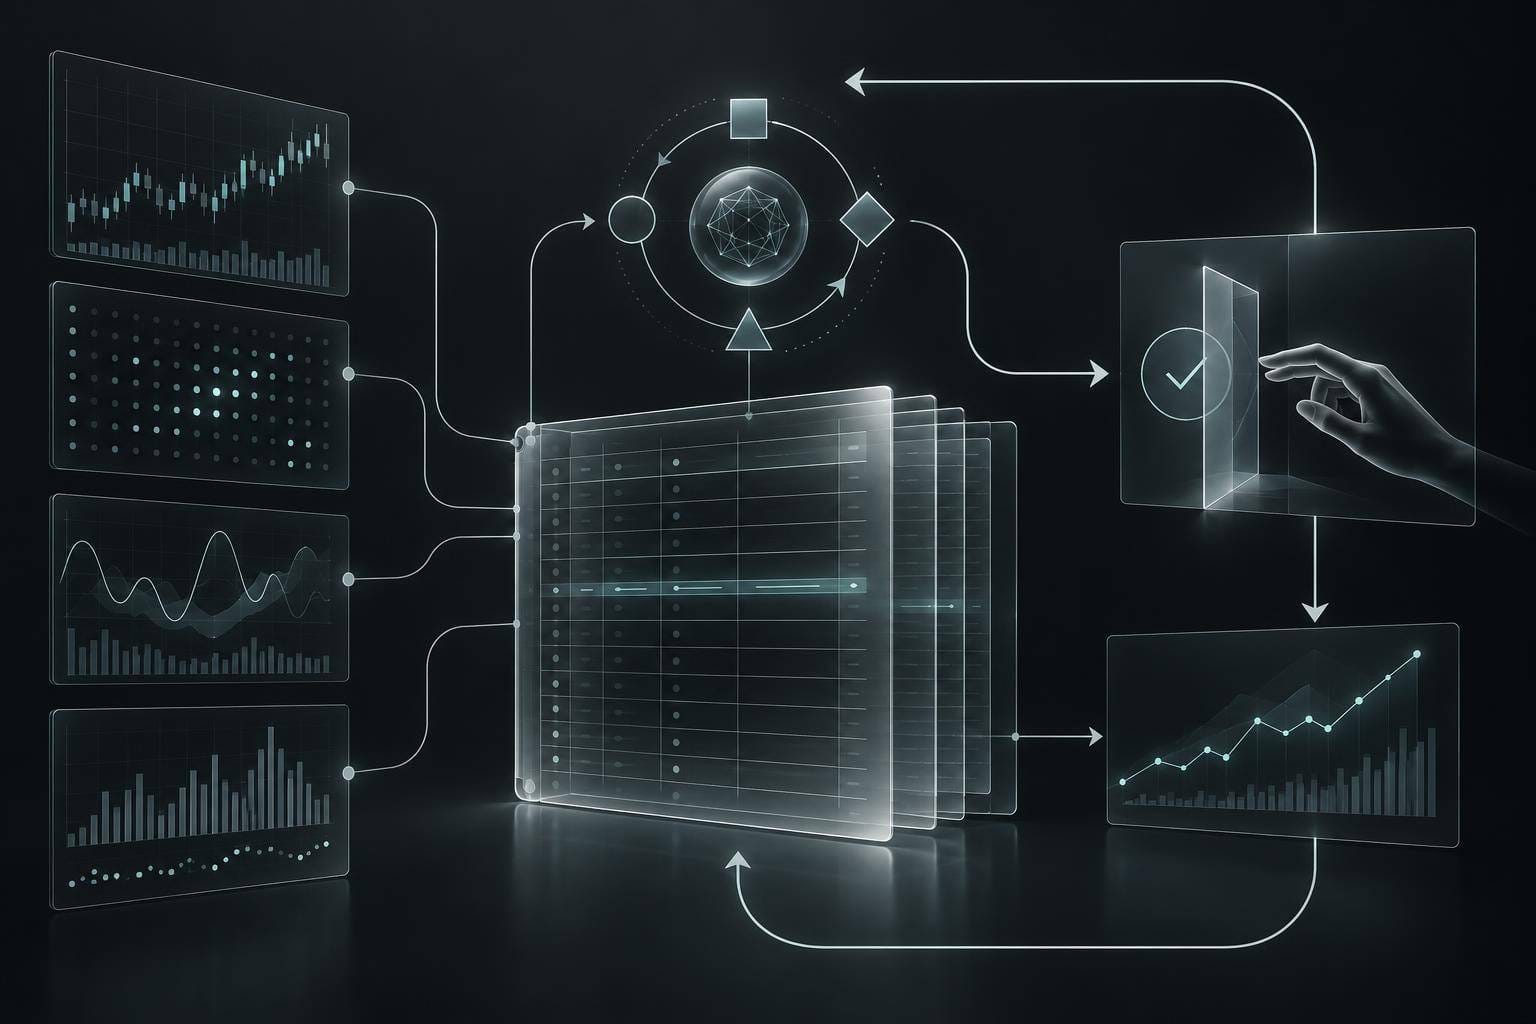
The next useful change in AI trading is not giving a language model a larger menu of tools. It is changing what counts as a test. Once an agent can observe market information, retrieve context, reason, emit an action, and adapt to feedback, a static backtest is no longer a sufficient description of the workflow. The research object becomes a time-stamped ledger of what the agent knew, what it decided, what execution meant, and what happened next.
That is the practical message from Agentic Trading: When LLM Agents Meet Financial Markets, a May 2026 arXiv survey that maps 77 studies and examines a primary subset of 19 closed-loop systems. Its audit finds protocol incomparability: only 2 of 19 report extractable time-consistent splits, one reports an explicit transaction-cost model, and none reaches its highest reproducibility level. These are not return results. They are evidence that the field’s bottleneck is evaluation design.
The market workflow is moving in the same direction. Robinhood now describes an agentic account connected through an MCP server that can explore ideas, build or rebalance portfolios, and place trades, with notifications and a dedicated budget. That is a product claim, not independent evidence that an agent is profitable or safe. But it makes the missing control concrete: before an agent is allowed near capital, the researcher needs a replayable paper-trading record.
From strategy backtest to decision ledger
The old workflow asks whether a rule produced a good historical curve. The new workflow asks whether an agent’s entire decision pipeline survives inspection. At minimum, each observation should record the market-data timestamp, the available universe, retrieved documents or signals, prompt and model version, proposed action, confidence or uncertainty, assumed order type, fill rule, fees and slippage, and the reason for any human override.
This is more than logging for its own sake. Without a point-in-time snapshot, a later replay may silently include a revised filing or a data vendor’s corrected history. Without execution semantics, “the agent bought” could mean an immediate fill, a next-bar fill, or an unfilled limit order. Without a separate feedback field, the system may learn from a price that was not actually observable when the decision was made. A clean ledger turns these ambiguities into fields a reviewer can challenge.
The arXiv survey’s findings suggest a useful division of labor. Let the model propose a structured hypothesis and the next observation to collect; let deterministic code enforce the time boundary, eligible universe, order simulation, and risk limits. Let a human review a sample of traces for unsupported claims and impossible information. The agent may adapt its analysis, but it should not be allowed to rewrite its evidence or its historical state.
This complements WisdomChain’s agentic trading evidence ledger and its decision-trace work. It also connects to the earlier filing triage workflow: in each case, the value is a reviewable queue or trace, not a persuasive prediction.
A seven-day paper-trading exercise
Run a seven-day, research-only test on a fixed historical replay or a live paper account. Do not connect a funded account, transmit orders, or treat the output as advice. Choose a predeclared universe and baseline: a simple fixed-weight rule or a buy-and-hold paper benchmark. Give the agent only information available at each timestamp. Require every proposed action to produce a ledger row before it can be simulated.
Measure four things: trace completeness, point-in-time citation validity, simulated implementation shortfall after fees and slippage, and the rate of human overrides or rejected actions. Also record calibration: when the agent labels a decision high confidence, does the subsequent paper outcome differ from its low-confidence decisions after the same costs? The output is a reproducibility report, not an alpha claim.
Stop at once if timestamps cannot be reconstructed, citations point to information published later, the agent changes the universe without a logged rule, simulated fills rely on unavailable liquidity, or a reviewer cannot reproduce a decision from the ledger. A seven-day window is a diagnostic observation period, not evidence of robustness. Extend only after the controls pass.
The limits are material. The survey is a working paper, its study set may reflect publication and selection bias, and its protocol coding cannot remove the non-stationarity of markets. Paper fills are not live fills; fees, latency, market impact, and crowding can change the result. A vendor or broker has an incentive to present capability clearly, while a research team has an incentive to highlight successful traces. Those incentives belong in the audit record too.
The core judgment is narrow: agentic trading should first be treated as an auditable decision-support workflow, not an autonomous return engine. Discretionary investors can practice reviewing traces. Systematic teams can separate model adaptation from deterministic execution controls. Builders can compete on reproducibility, failure reporting, and safe stopping—not just on how confidently an agent speaks. The workflow has changed when every simulated action can answer four questions: what was known, what was assumed, what was done, and what would invalidate the result.
Sources: Wang et al., “Agentic Trading: When LLM Agents Meet Financial Markets”; Robinhood, “Agentic Trading”.