AI Practice Field Notes Turn Feedback Into Agent Memory Turn reviewed corrections into reusable agent principles, then test whether they transfer.
AI Practice Field Notes 把用户遇到的失败变成测试 生产环境中的失败只是候选测试,并非天然可靠的基准。借鉴 Replit 对评估闭环的描述,把经过审核、能够复现的案例变成下一次改进的证据。
AI Practice Field Notes Turn User Failures Into Tests A production failure is a candidate test, not yet a trustworthy benchmark. Replit’s evaluation loop suggests how to turn reviewed, reproducible cases into evidence for the next change.
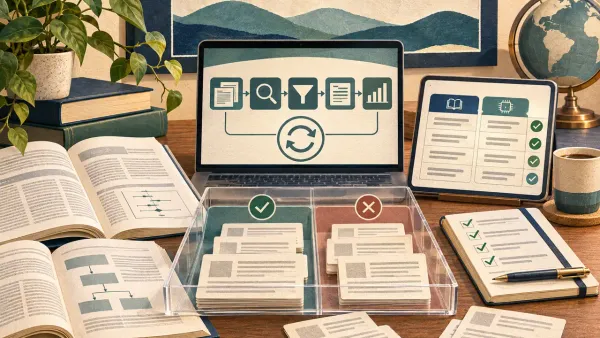
AI Practice Field Notes AI 能复现系统综述吗? 评估 AI 文献筛选与信息提取,关键不只是准确率数字,而是参照集、标准和错误复核是否可靠。本文给出一个有边界、可审计的本地检验方案。
AI Practice Field Notes Can AI Reproduce a Literature Review? A systematic-review benchmark is only as useful as its reference set, criteria, and error checks. Here is a bounded way to evaluate AI screening and extraction without mistaking vendor results for your own.
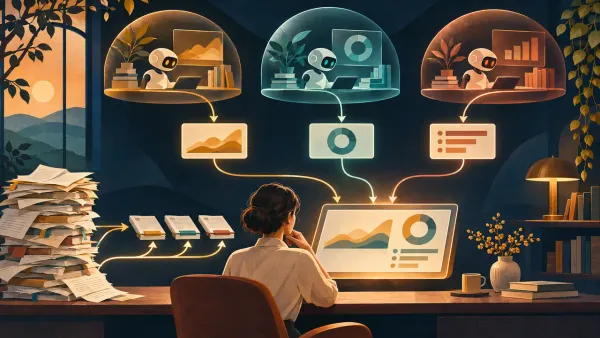
AI Practice Field Notes Subagents Are Compression Delegate bounded exploration to a fresh context, then review an evidence-linked summary.
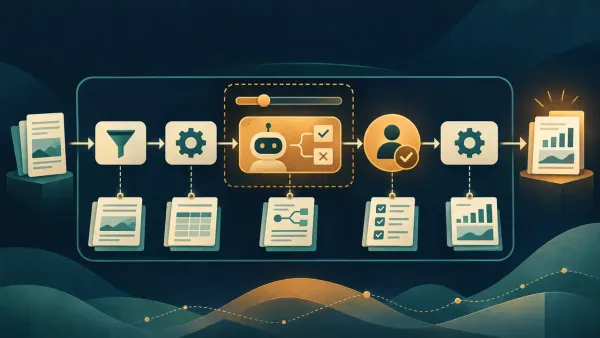
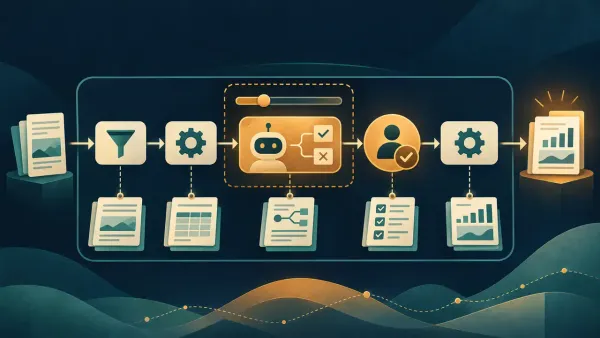
AI Practice Field Notes Count the Uncertain Decisions, Not the Agents A field guide to placing a model inside deterministic workflows—and testing whether that boundary actually helps.
AI Practice Field Notes Stop Prompting Harder When an agent stalls, inspect its tools, context, and feedback loops before repeating the prompt.
AI Practice Field Notes The Agent Is a Workflow, Not a Prompt Learn AI from practitioners by studying the workflow, reconstructing the smallest useful experiment, and measuring results before copying the tool stack.
AI Practice Field Notes Find the First Wrong Step A practical evaluation loop: judge end-to-end success first, then use traces to find the earliest consequential failure. Our proposed reconstruction remains unrun because no baseline traces were available.