Turn User Failures Into Tests
A production failure is a candidate test, not yet a trustworthy benchmark. Replit’s evaluation loop suggests how to turn reviewed, reproducible cases into evidence for the next change.

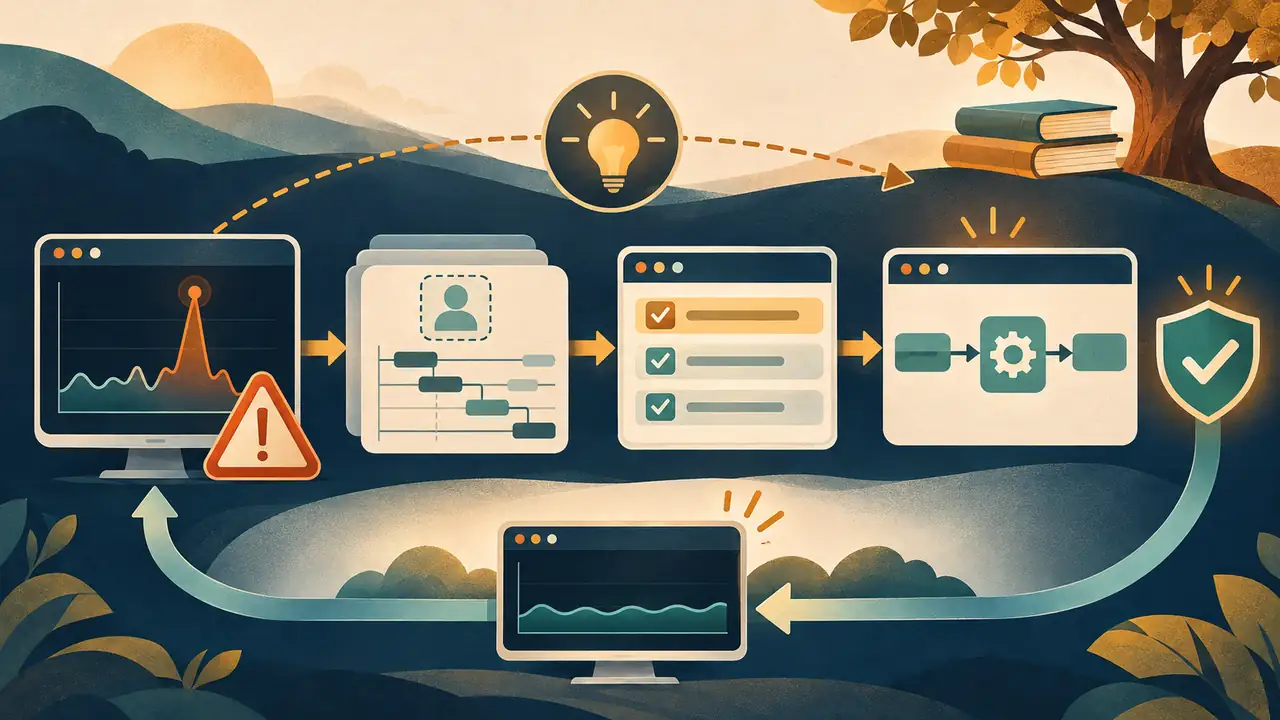
When an AI agent fails for a user, the tempting response is to patch the prompt and move on. But a fix that cannot be reproduced may solve one anecdote while leaving the underlying failure untouched—or quietly break a different task. Replit’s account of evaluating and improving Agent at scale offers a more disciplined framing: treat offline benchmarks, online A/B tests, and production traces as different, complementary signals in a continuing improvement loop, rather than asking one score to stand in for all evidence (Replit, “Closing the loop”).
That is a reported description of Replit’s approach, not evidence that the same metrics or process will work unchanged for a small team. The transferable lesson is narrower: a recurring, consented failure can become a useful evaluation case only after someone can describe it safely, reproduce it, and decide what outcome counts as better.
The signal
- Practitioner / team: Replit Agent.
- Source: Replit’s first-party account of evaluating and improving Agent at scale.
- Why it matters: A static launch benchmark can miss new failure patterns, while a production anecdote is too messy to compare candidates by itself. The loop needs both controlled checks and evidence from actual use.
A failure is raw material, not a test
A trace may contain private data, accidental context, or a sequence that cannot be replayed. Copying it wholesale into a benchmark risks privacy exposure and overfitting. Instead, begin with permission and minimization: retain only the steps and fields needed to understand the failure, replace identifying details, and have a reviewer confirm the sanitized case still represents the problem. If consent is absent or the example cannot be de-identified, stop; do not turn it into training or evaluation material.
Next, write the task as an observable contract. “The agent was frustrating” is not a test. “Given a request to add a settings page, the agent must preserve existing routes, implement the page, and report the files changed” is closer: it names an input and behaviors a reviewer can check. Keep the original failure mode, expected behavior, allowed tools, and grading rubric together. A case without a clear expected outcome invites a score that measures reviewer preference rather than user-relevant success.
Then establish a baseline. Run the fixed case set against the current version using the same instructions, environment, and rubric. Record not just pass/fail but the specific failure category, human review notes, latency or cost when relevant, and version identifiers. This creates a comparison point. Add the new sanitized case to a small offline suite and evaluate candidate changes against both it and existing cases; a targeted win that causes regressions elsewhere is not a clear improvement.
Only changes that satisfy the predeclared offline checks should be considered for an online A/B comparison, if the team has a suitable experiment design and sufficient traffic. Offline results answer a constrained question about reproducible tasks. Online comparisons can reveal behavior in real usage, but they bring sampling, allocation, and interpretation problems. Production traces help discover what to test next; they do not, on their own, prove that a change caused better user outcomes. Replit describes these signals as complementary, not interchangeable.
Reconstruction plan (HYPOTHESIS; not run)
- Task: Take five small app specifications and a small, privacy-safe set of failure examples. The five tasks are a proposed bounded exercise, not a Replit-reported experiment.
- Baseline: Run the current agent version on a fixed rubric before adding failure-derived cases.
- Variant: Add only reviewed, reproducible cases; compare candidate changes on the expanded offline suite. Reserve any online comparison for candidates that pass the offline gate.
- Artifact: Sanitized cases, consent/de-identification review, rubric, versioned results, reviewer decision, and monitoring plan.
- Success condition: The cases expose repeatable, user-relevant regressions and improve the quality of the next change decision without unacceptable cost or latency.
- Stop condition: No permission to use the traces, insufficient de-identification, irreproducible failures, or unclear grading criteria.
This reconstruction has not been run. No local evaluation, A/B test, or user-impact result is established here. Risks include selection bias (the loudest failures dominate), leakage of sensitive information, overfitting to a handful of cases, and optimizing a proxy score while users still struggle. A small team should also account for the ongoing cost of maintaining cases as the product and task distribution change.
Transfer rule
Try this when failures recur, can be used with appropriate permission, and can be represented as a stable task with a defensible expected outcome. Avoid it when examples are sensitive, isolated, impossible to reproduce, or too ambiguous to score. Revisit the recommendation if later online evidence contradicts the offline ranking, or if the case set stops reflecting current user work.
Practice card
- Inputs: Consented, minimized failure examples and a written task contract.
- Steps: Sanitize and review; define expected behavior; run a baseline; add cases to the offline suite; compare candidates; consider online evidence only after the offline gate.
- Expected output: A versioned case, rubric, results, and explicit decision record—not a claim of impact.
- Quality check: Can another reviewer reproduce and grade the case without seeing private data?
- Next iteration: Examine disagreements and new failure patterns, then add cases only when they represent a repeatable user need.
For the Chinese companion, see 把用户遇到的失败变成测试. Related: Find the First Wrong Step.
Links / sources
- First-party source: Replit, “Closing the loop: Evaluating and improving Replit Agent at scale”