The Next Investment AI Test Is a Reproducible Research Trail
Agentic research can compress discovery, but its durable value depends on a dated trail of sources, claims, checks, and human decisions.

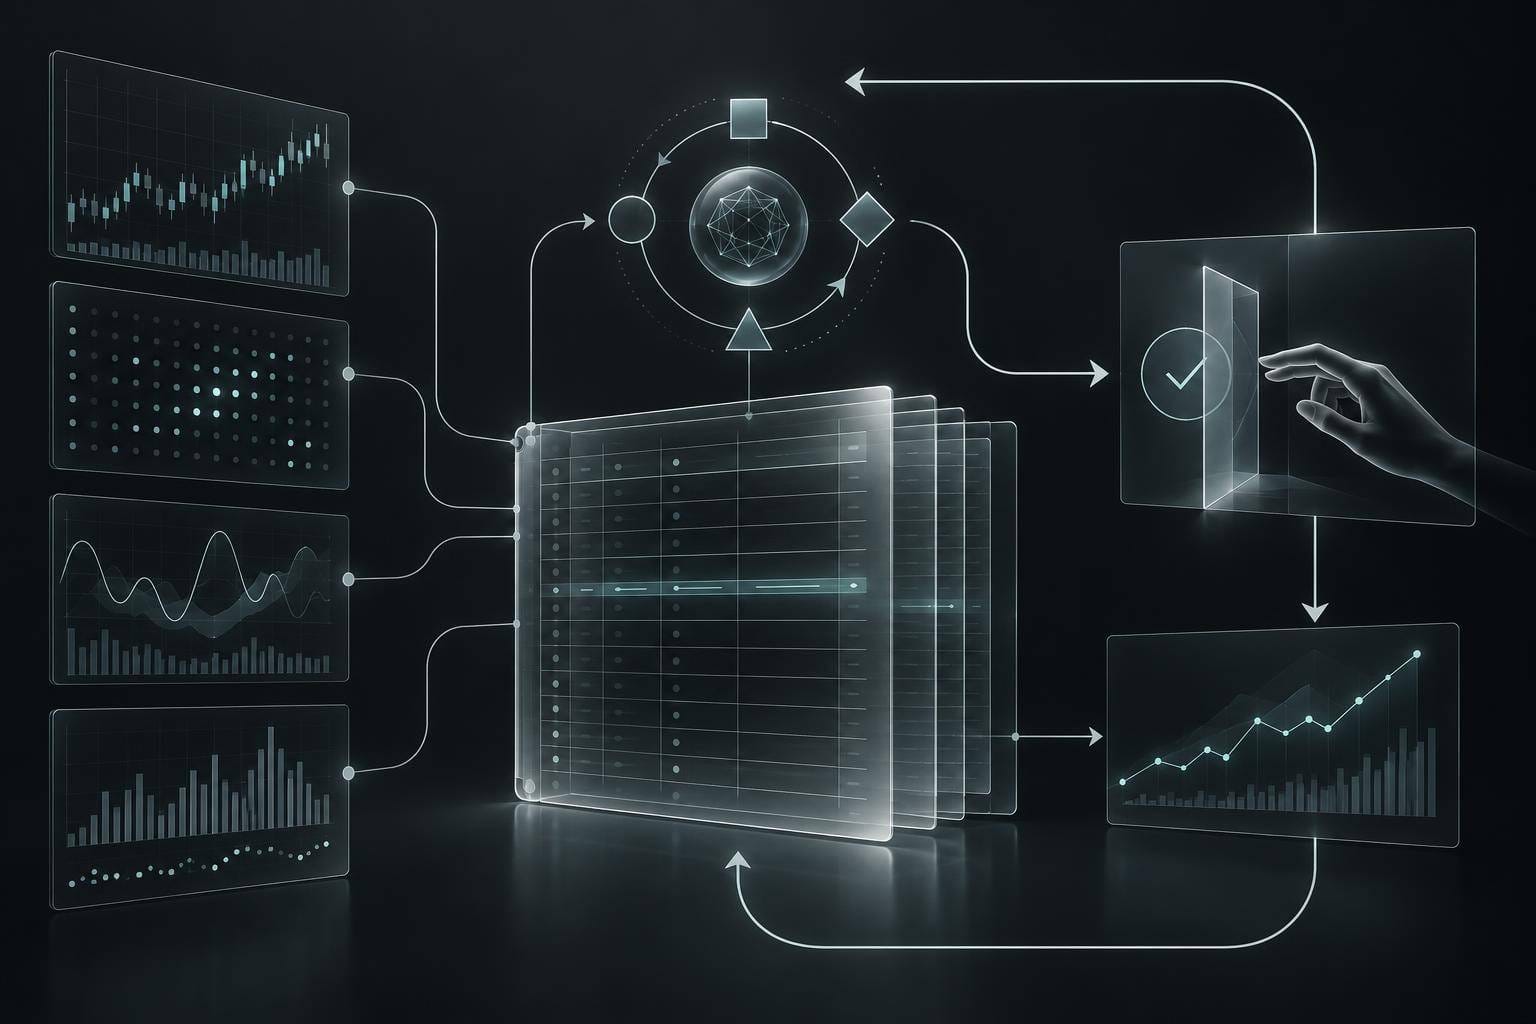
AI can make an investment research desk look dramatically faster while making it harder to answer a basic question: what exactly produced this conclusion? The useful change is not an agent that writes a polished memo. It is a workflow that turns a research question into a dated, inspectable trail of sources, claims, tests, and human decisions.
That judgment follows two current signals. Robeco describes agentic research as helping investors scan papers, extract claims, summarize methods, and decide what deserves deeper review. A 2026 finance deployment guide from Aleph makes the operational point: agents are valuable when they connect data, reasoning, and action, but weak data foundations and missing audit controls remain the main barriers. These are different source types—an asset manager’s workflow account and a vendor’s implementation view—so neither should be treated as proof of investment performance.
The old workflow was linear: an analyst searched, read, took notes, and wrote a view. The new workflow can be branching. An agent retrieves documents, maps claims to passages, compares methods, proposes follow-up checks, and queues unresolved contradictions. That changes the unit of work from “a memo” to “a research trail.” The trail is useful only if another analyst can reproduce its inputs and see where judgment entered.
What the changed workflow looks like
Start with a narrow question, such as whether a reported model improvement survives a time-ordered validation. Give the system a source list and a cut-off date. Ask it to produce four linked objects: the exact claim, the supporting passage, the method and sample, and a list of missing information. A second pass should try to falsify the claim by searching for different data, horizons, or definitions. The human then accepts, rejects, or parks each item, with a reason and timestamp.
This design separates retrieval from judgment. The model can find duplicated terminology, normalize tables, and flag contradictions. It cannot establish that a backtest is free of leakage, that a vendor’s benchmark reflects production conditions, or that a selected sample represents the opportunity set. A citation is evidence of what was written, not evidence that the result is economically meaningful.
The practical output is a queue: claims ready for replication, claims blocked by missing data, and claims that should not influence a decision. This connects to the earlier auditable research queue and the warning that AI advice needs a grounding test. In both cases, the safeguard is traceability, not a more confident paragraph.
A 60-minute research-only test
Use one public paper or company filing and a fixed research question. The baseline is a conventional manual note containing five claims and their citations. For the AI condition, ask an agent to extract the same five claims, record source passages and dates, identify one counterargument per claim, and produce a review queue. Do not place orders or use the output as a recommendation.
Measure citation completeness, claim-to-passage agreement, time to a reviewable packet, and the number of unsupported or duplicated claims. Have a human blind-review both packets for reproducibility: can a second reader locate the evidence and understand the limitation? Stop if the agent invents a source, cannot preserve dates, or causes the reviewer to accept a claim without checking the underlying passage. A seven-day paper-trading extension is unnecessary; this test is about research quality, not returns.
The uncomfortable limits
The workflow can improve documentation without improving decisions. Selection bias enters when only easy-to-retrieve papers become the queue. Reporting bias enters when a vendor highlights successful deployments. Measurement bias enters when “time saved” is recorded but correction effort is not. Agent traces can also create false comfort: a long chain of citations may still share one original error.
There are causal gaps too. A better audit trail does not prove alpha, and a faster review cycle can increase overconfidence or crowding. Data revisions, regime changes, licensing limits, latency, and model updates can break reproducibility. Incentives matter: a platform selling autonomy benefits from emphasizing completed tasks, while an investment team bears the cost of errors.
For discretionary investors, the practice is to demand claim-level evidence before adopting a conclusion. Systematic teams should version prompts, retrieval sets, and evaluation windows. Builders should treat the research trail as a product requirement: immutable inputs, explicit uncertainty, human overrides, and a failure queue. The frontier is not autonomous conviction. It is research that remains inspectable after the model, data, and market regime change.
Sources: Robeco, “Agentic AI and research”; Aleph, “AI agents in finance”.