AI Monitoring Is Useful Only When It Shows What Changed
AI can watch a research universe continuously, but the useful output is an auditable change log—not a stream of unexplained alerts.

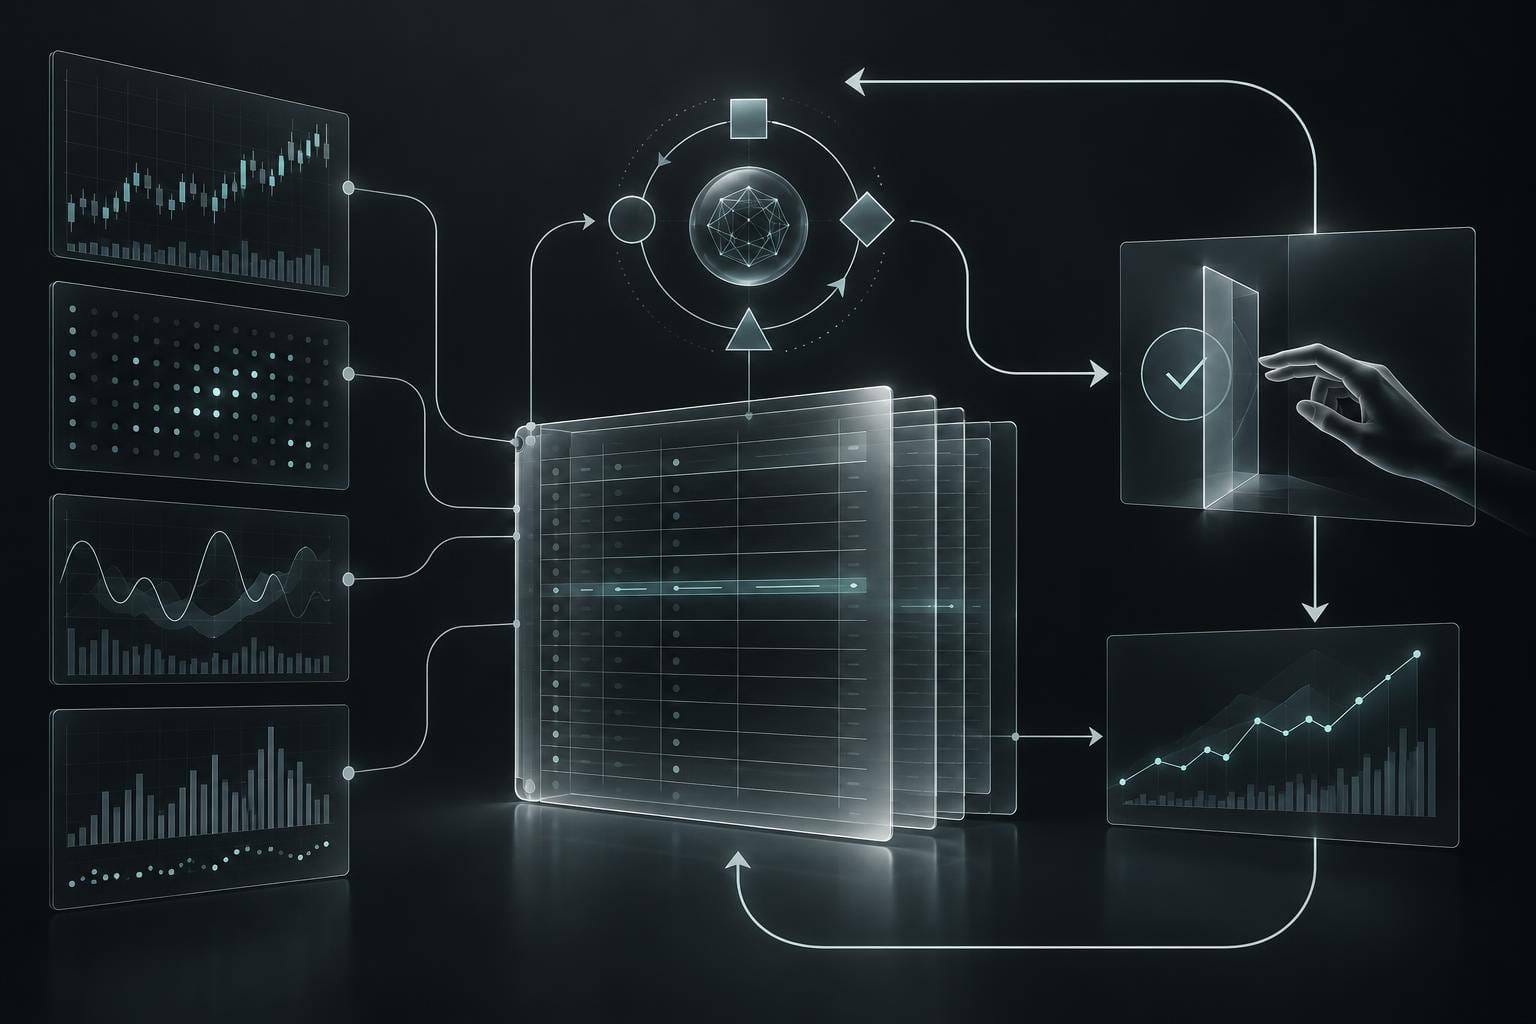
The next useful step for AI in investment research is not another alert. It is a dated explanation of what changed, which evidence caused the change, and what a human still needs to check.
That distinction matters because continuous monitoring changes the unit of work. A traditional analyst periodically opens filings, transcripts, estimates, and risk reports. An AI-assisted desk can compare new documents with a prior snapshot, cluster related changes, and place the highest-priority items in a queue. The gain is not a prediction. It is a narrower, more inspectable review task.
The judgment is simple: AI monitoring is worth testing when it creates a reproducible change log. It is dangerous when it converts uncertain language into an urgent-looking score with no timestamp, source passage, or abstention rule.
This is consistent with the direction of regulatory concern. The SEC’s 2024 predictive-data-analytics proposal described conflicts that can arise when firms use models to optimize for investor interests other than the investor’s interest, while FINRA’s generative-AI guidance emphasizes existing supervision, privacy, and recordkeeping obligations. Neither source proves that a particular monitoring system works. They do establish why provenance and controls belong inside the workflow rather than in a later compliance review.
From alert inbox to evidence ledger
An auditable monitoring loop has five parts. First, define a stable universe and a cutoff time. Second, collect only documents that were available by that time. Third, compare the new text or data with the prior snapshot. Fourth, ask the model to produce a structured record: claim, source URL, publication time, changed passage, confidence, and “needs human check” reason. Fifth, have a reviewer accept, reject, or defer the item while preserving the original evidence.
The model can help with semantic comparison, duplicate grouping, and plain-language summaries. It should not silently decide that a management statement is material, that a risk has increased, or that an event implies a trade. Those are judgments whose definitions vary by mandate, data quality, and horizon.
The technical trap is that “change” is not the same as “importance.” A new sentence may be boilerplate. A small numerical revision may matter more than a long narrative. A model may also treat a rewritten document as new information, miss a scanned attachment, or rank items according to the language style of a prolific issuer. A good system therefore exposes the comparison window and lets a reviewer see both the old and new evidence.
Research on language models in finance is often evaluated on curated tasks or historical data. That can show whether a method is feasible, but it does not establish live monitoring quality. Selection bias, survivorship bias, reporting delays, changing document formats, and alert-fatigue effects all create causal gaps. Vendor demos have another incentive: they showcase recall and speed, while the cost of false positives and the operational burden of review may be less visible.
For a related workflow, see The Agentic Research Desk Needs an Auditable Queue Before It Needs Autonomy and AI Can Turn Earnings Calls Into a Research Queue—If the Queue Is Auditable.
A bounded research exercise
Run a seven-day paper-only test on a fixed universe of 10–20 instruments. Freeze the universe and record the document cutoff each day. Build two queues: a simple keyword-and-time baseline, and an AI-assisted semantic-difference queue. For every item, log source availability time, the changed passage, reviewer verdict, review minutes, duplicate rate, and the share of alerts that contain a verifiable new fact.
Do not place orders or infer expected returns. The output is a labeled ledger. Compare precision at the top 10 items, time per reviewed item, omission rate on a manually sampled set, and reviewer agreement. A useful baseline is the keyword queue with the same document universe and cutoff. Stop after seven calendar days—or immediately if timestamps cannot be reconstructed, source passages are missing, or the AI queue cannot abstain when evidence is ambiguous.
Even a favorable result is local evidence, not proof of investment value. The observation window is short, the sample is selected, and the reviewer learns the system’s patterns. Production use would require access controls, retention, vendor-change monitoring, escalation procedures, and tests across quiet and event-heavy periods. The right lesson is narrower: AI can compress document comparison, but the durable asset is a verifiable record of why an item entered the queue.
Sources: SEC, Conflicts of Interest Associated with the Use of Predictive Data Analytics by Broker-Dealers and Investment Advisers; FINRA, Generative Artificial Intelligence: Questions and Answers.