AI Agents Meet the Last Exam: Workflow Proof Is the New Capability Test
New agent benchmarks and frontier-lab programs point to the same operational reality: capability claims matter only when agents complete long-horizon work with verifiable outcomes.

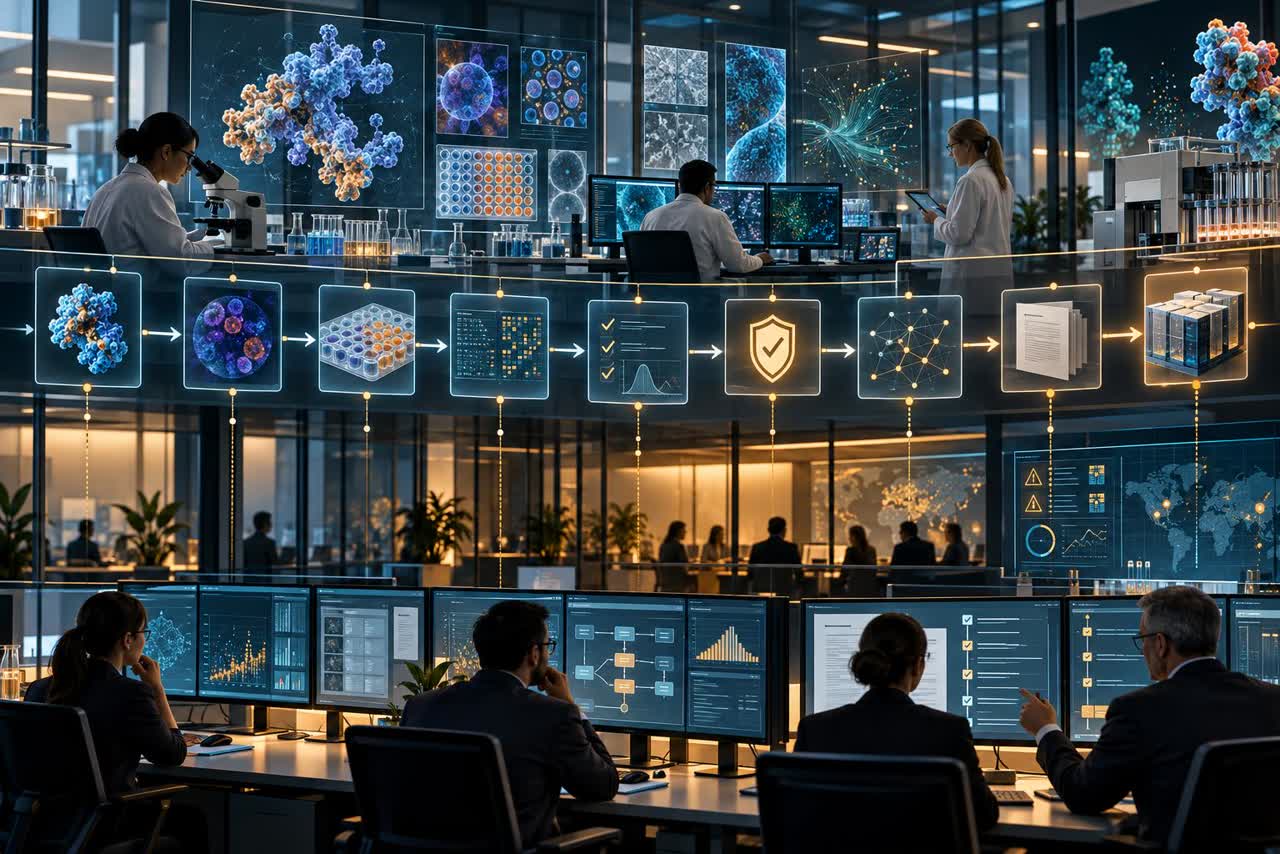
An agent can now pass a polished demo, call tools, and produce a plausible report. The harder test is whether it can finish a messy, economically meaningful task when the goal is explicit, the path is not, and the result can be checked.
The important thing is not that AI agents are becoming more autonomous; it is that the industry is finally moving capability claims toward workflow-level proof, because benchmark scores and activity logs do not yet establish dependable work.
That shift is visible in two places this month. The research paper Agents’ Last Exam introduces a benchmark for long-horizon, economically valuable tasks with verifiable outcomes, developed with more than 250 industry experts. Separately, EvalResearchBench asks whether agents can design their own evaluations, motivated by the cost and slowness of repeatedly running complex tests. At the company level, Anthropic says it is expanding its AI-for-Science program through partnerships with 20 scientific institutions and research groups. Google DeepMind’s current public research surface likewise emphasizes models, science, and responsibility rather than a single “agent intelligence” number.
The signal is not that agents have solved work. It is that the unit of competition is changing from a model response to an accountable workflow.
Evidence cards: voices and signals
Dario Amodei — organizational context
Accurate paraphrase, not a personal quote: Anthropic announced an expansion of its AI-for-Science partnerships. Date/venue: October 28, 2026, Anthropic newsroom. Claim/mechanism: connecting models to scientific workflows is intended to create practical research leverage, but the mechanism still depends on expert review and measurable outcomes. Evidence grade A (company announcement): https://www.anthropic.com/news
Demis Hassabis — organizational context
Accurate paraphrase, not a personal quote: Google DeepMind’s October research surface places frontier models beside science and responsibility work. Date/venue: October 2026, Google DeepMind research blog. Claim/mechanism: capability programs are being framed as systems with application and responsibility layers, but a landing page cannot establish task performance. Evidence grade A (organizational research page): https://deepmind.google/blog/
Yejin Choi — academic lane context
Accurate paraphrase, not a personal quote or authorship claim: recent agent-evaluation research makes long-horizon, verifiable outcomes the measurement target. Date/venue: October 2026, arXiv papers Agents’ Last Exam and EvalResearchBench. Claim/mechanism: outcome-based and better-designed evaluations can expose failures hidden by short demos, while self-generated tests require held-out review. Evidence grade A (primary papers): https://arxiv.org/abs/2606.05405 and https://arxiv.org/abs/2610.04184
The benchmark is getting closer to the job
The Agents’ Last Exam authors define a useful correction to ordinary demos: tasks should be long-horizon, economically relevant, and judged by outcomes that can be verified. That design matters because a short answer can look correct while hiding an incomplete plan, an unrecorded side effect, or a human who silently repaired the result. The benchmark is a primary academic source, but its construction is not proof of production reliability. It is a proposal for better measurement.
That distinction connects to EvalResearchBench. Its research question is whether agents can help design evaluations for recursive self-improvement. The implied mechanism is attractive: if evaluation is a bottleneck, agents might reduce the cost of creating tests. The limitation is equally important: an agent that writes a plausible rubric may still encode the wrong objective or reward easy-to-measure behavior. Evaluation generation needs adversarial review and held-out tasks, not just faster test creation.
The two papers therefore agree on the direction but not on the shortcut. Better evaluation is necessary; self-authored evaluation is not automatically trustworthy.
Frontier labs are adding context, not a verdict
Anthropic’s October 28 announcement about 20 AI-for-Science partners is a concrete deployment signal: organizations are trying to connect models to research workflows. It does not show that the resulting systems discover better science, reduce cycle time, or operate without expert intervention. The announcement is an organizational claim, not a personal statement from a rostered executive, so it is useful evidence of direction and investment—not of outcome. Anthropic’s announcement stream is the primary source.
Google DeepMind’s public research page presents a similar pattern: frontier models are being discussed alongside science and responsibility. That is relevant context, but a landing page cannot establish comparative capability. The stronger evidence remains task-level evaluation, reproducible baselines, and logs of what happened after deployment. Google DeepMind’s research updates provide the primary context.
This is a forecast-and-measurement disagreement, not a personality conflict. Labs have incentives to show breadth and momentum; benchmark authors have incentives to expose failure modes. The benchmark side currently has the stronger evidence for the narrow claim that workflow-level tests are needed, because it specifies tasks and outcomes. The unresolved claim is whether passing such tests predicts durable value across organizations.
Chief Data Scientist Review
Observed variables include task completion, outcome validity, recovery behavior, human interventions, latency, and cost. “Agent completed the task” is not a causal explanation of value. A team must compare the agent with a skilled human baseline, a scripted workflow, and a simpler model over the same time horizon. Otherwise selection bias favors tasks chosen because agents already look good, while reporting bias hides abandoned runs.
For the next 30–90 days, instrument one workflow with an immutable task ID, action log, approval points, rework time, and outcome label. Track: (1) verified completion rate, (2) human correction minutes per task, and (3) cost per accepted outcome. Use a 10% improvement in accepted outcomes at no more than 20% extra cost as a success threshold. Stop or revise the deployment if severe errors rise, if correction time exceeds the manual baseline, or if the metric improves only because low-value tasks are being selected.
The practical consequence spans the stack. Data teams need outcome labels, not just interaction telemetry. Model teams need held-out, adversarial tasks. Product teams need recoverable state and explicit approval boundaries. Operations teams need incident and rework accounting. Governance teams need an audit trail that survives model changes. The agent-control-plane analysis and the test-harness bottleneck analysis explain why these controls are becoming product infrastructure.
Watch next, then act
Watch whether independent teams reproduce Agents’ Last Exam results on new agent architectures; whether self-generated evaluations survive expert and held-out review; and whether Anthropic’s science partnerships publish measurable outcomes rather than participation lists. These indicators can verify or falsify the central claim within one to three quarters.
One operator action is concrete: choose one costly workflow, freeze a representative task sample, define “accepted outcome” before testing, and run the agent beside the existing process for four weeks. Do not ask whether the agent is impressive. Ask whether it produces more verified work, with less correction, at a cost the business would actually pay.
The opening situation has not disappeared: demos remain easy. The decision has changed. Treat every new agent as a candidate worker that must sit an outcome-based exam before it receives production authority.
Sources
- Agents’ Last Exam (arXiv, October 2026)
- EvalResearchBench (arXiv, October 2026)
- Anthropic Newsroom
- Google DeepMind Blog